CONCEPT INTERFACERAG system
RAG Document Assistant
RAG-powered document search with source-grounded answers.
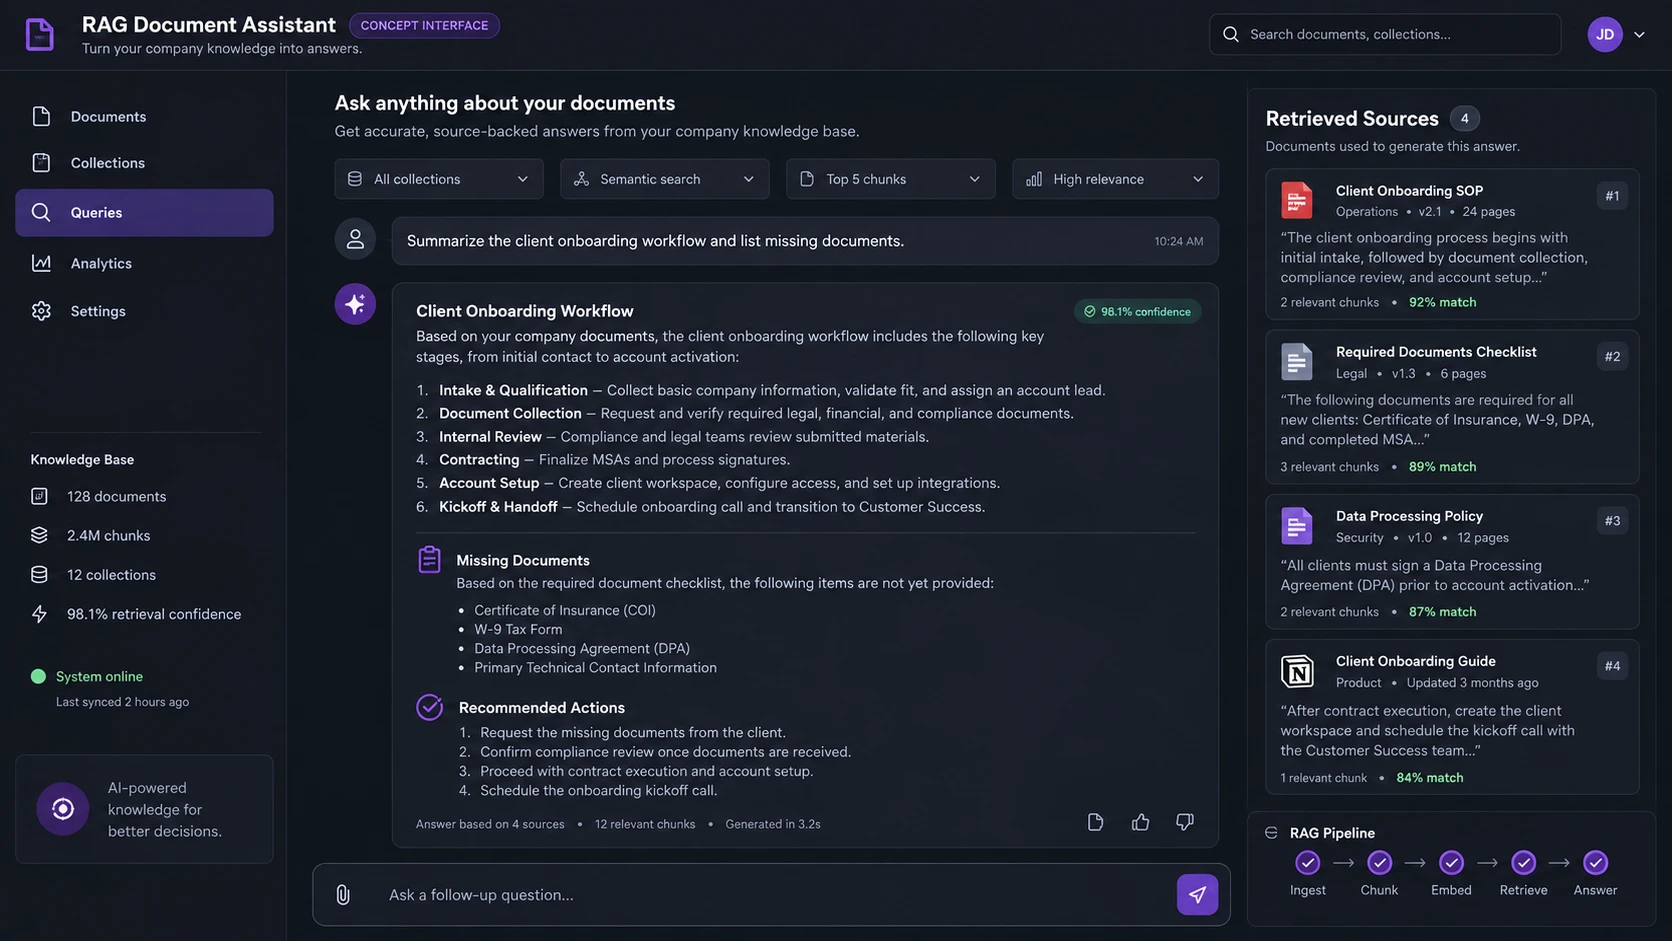
Swipe or use arrow keys to inspect the full interface.
Interface concept. Figures shown — document and chunk counts, confidence and match scores, timings — are placeholder values; no live data source or production deployment is connected.
01 · Product premise
Ask a question in plain language and get an answer written from your own documents — with the sources shown next to it, so the answer can be checked rather than trusted.
The class of business problem it addresses: internal knowledge search, questions about procedures, offers or policies, and support documentation — anywhere staff or customers need a checkable answer from a company's own documents. These are the kinds of application this pattern fits, not deployments claimed here.
02 · Document ingestion
Documents of common types are added to named collections. Each is prepared for search on the way in, and the interface keeps the document list one glance away.
03 · Chunking + embeddings
Long documents are split into passages that keep their metadata, then turned into embeddings so meaning — not just keywords — can be searched.
04 · Storage / indexing
Embeddings are stored in a semantic index alongside the source reference of each passage, which is what lets an answer point back to where it came from.
05 · Retrieval
A question is matched against the index, and the most relevant passages are retrieved and reranked before any answer is written.
06 · Answer with sources
The answer is composed from the retrieved passages only, with numbered citations inline. The point of the design is that an answer is never shown without the material it was built from.
07 · Source inspection / citations
Every citation resolves to a source entry: the document, the page, and a relevance indicator. A reader can check the claim against the source in one step.
08 · Architecture pipeline
Six stages, one direction — the same pipeline the interface concept presents. The highlighted stage is the one the reader actually sees.
- IngestionUpload documents
- ChunkingSplit with metadata
- EmbeddingGenerate embeddings
- Storage / indexingSemantic index
- RetrievalSearch and rerank
- Answer with sources — key stageCited answer
09 · Current status
CONCEPT INTERFACE · NOT A DEPLOYMENT
Presented as a portfolio case-study visual. It is not a claim of a live client deployment, production scale, or measured retrieval quality, and no specific embedding or storage technology is claimed.